DeepSeek unveils an experimental version of its V4 Flash model that can understand visual prompts, saying it nears the performance of Anthropic's Opus 4.8 (Bloomberg)
ThinkingNews Desk · how this was written
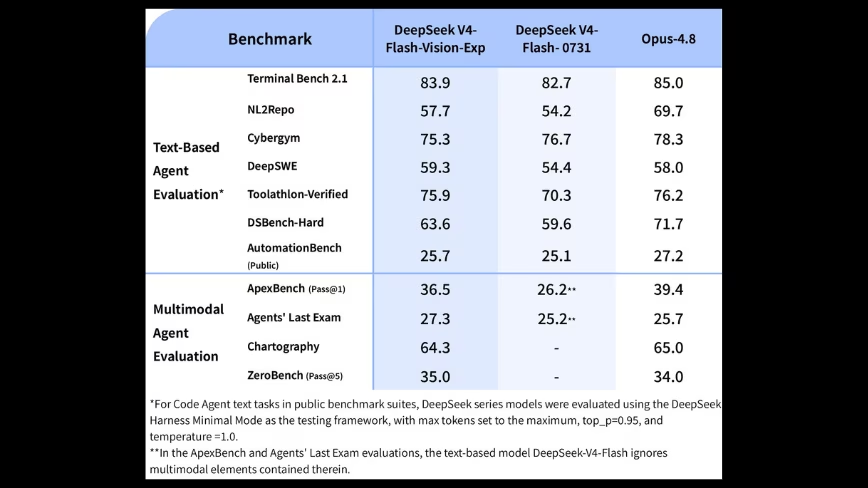
DeepSeek has launched an experimental multimodal version of its V4 Flash model that can process visual prompts. The company says the new model’s capabilities are close to those of Anthropic’s Opus 4.8, positioning it as a direct competitor in the emerging visual-AI space.
Written from all 3 reports below, not from any single one.
How it was reported
- Hacker News·DeepSeek-v4-flash-vision-exp
The deepseek-flash model accepts JPEG, PNG, GIF, and WebP images, detecting format from content and routing requests through the current Flash model even with the legacy name deepseek-v4-flash-vision-exp. Images may be provided as base64 data URLs, external URLs (≤32 MiB, ≤8192 characters, 60-second download), or via the Files API using a file_id (≤64 MiB). For image_url inputs, an optional “detail” parameter controls processing depth.
- The Next Web·DeepSeek launches an experimental multimodal model to rival Anthropic
DeepSeek unveiled an experimental multimodal model, DeepSeek-V4-Flash-Vision-Exp, which extends its text-only V4-Flash system with image and screenshot reading capabilities and is now accessible via the company’s API platform. The model’s agent performance is reported to be close to Anthropic’s Opus-4.8, and according to DeepSeek’s own benchmark table it surpasses Opus-4.8 on three of eleven evaluated tasks.
- TechMeme·DeepSeek unveils an experimental version of its V4 Flash model that can understand visual prompts, saying it nears the performance of Anthropic's Opus 4.8 (Bloomberg)
DeepSeek released an experimental multimodal version of its V4 Flash model that can process visual prompts. The company asserts that the model’s performance on multimodal agentic benchmarks approaches that of Anthropic’s Opus 4.8, indicating a comparable level of capability in visual-language tasks.
Related stories
- Three reasons why DeepSeek’s new model V4 matters8 outlets
- DeepSeek launching v4.1 flash cheaper and more capable than v4 pro3 outlets
- DeepSeek releases DeepSeek Harness under the MIT license in developer preview, touting a design where "every capability is a plugin" that can be swapped out (Carl Franzen/VentureBeat)3 outlets
- DeepSeek made AI cheap. Now it is raising $8bn and buying robots3 outlets